
पहली एंट्री हमेशा पिन का सोर्स होती है। कुल कॉन्फ़िडेंस एक भारित औसत है कि हर संदर्भ ऊपर इस्तेमाल किए गए शुरू और खत्म होने के समय का कितनी मज़बूती से समर्थन करता है; सबसे नए संदर्भ से हर 180 दिन पुराना होने पर किसी संदर्भ की गिनती आधी हो जाती है।
Google's own post, dated 18 November 2026, says Gemini 4 Neon is rolling out today.
Google DeepMind's model card linked from the announcement.[1]
Google's post on the safety and security approach for the Gemini 4 family, linked from the announcement.[1]
Google's announcement of the lower-cost sibling model released 12 November 2026.[1]
Google's post on the top-tier Gemini 4 Carbon model, the sibling above Neon.[1]
कुछ छूट गया या गलत है? अपने शब्दों में बताएं: कोई लिंक जो इस पिन का समर्थन करता हो, कोई अलग शुरुआत या खत्म होने की तारीख और उसकी वजह, या कोई तथ्य जो छूट गया हो या गलत हो। AI इसे इस पिन के सोर्स से मिलाकर जांचता है, बेहतर सोर्स खोजता है, और जो भी पेज आपकी बात का समर्थन करता है उसे जोड़ देता है। पिन के अपने सोर्स की अहमियत फिर भी सबसे ज़्यादा रहती है। AI तस्वीरें भी देखता है: जो तस्वीर कुछ और दिखाती हो या ठीक से न दिखाती हो, उसे नीचे कर दिया जाता है या बदल दिया जाता है।
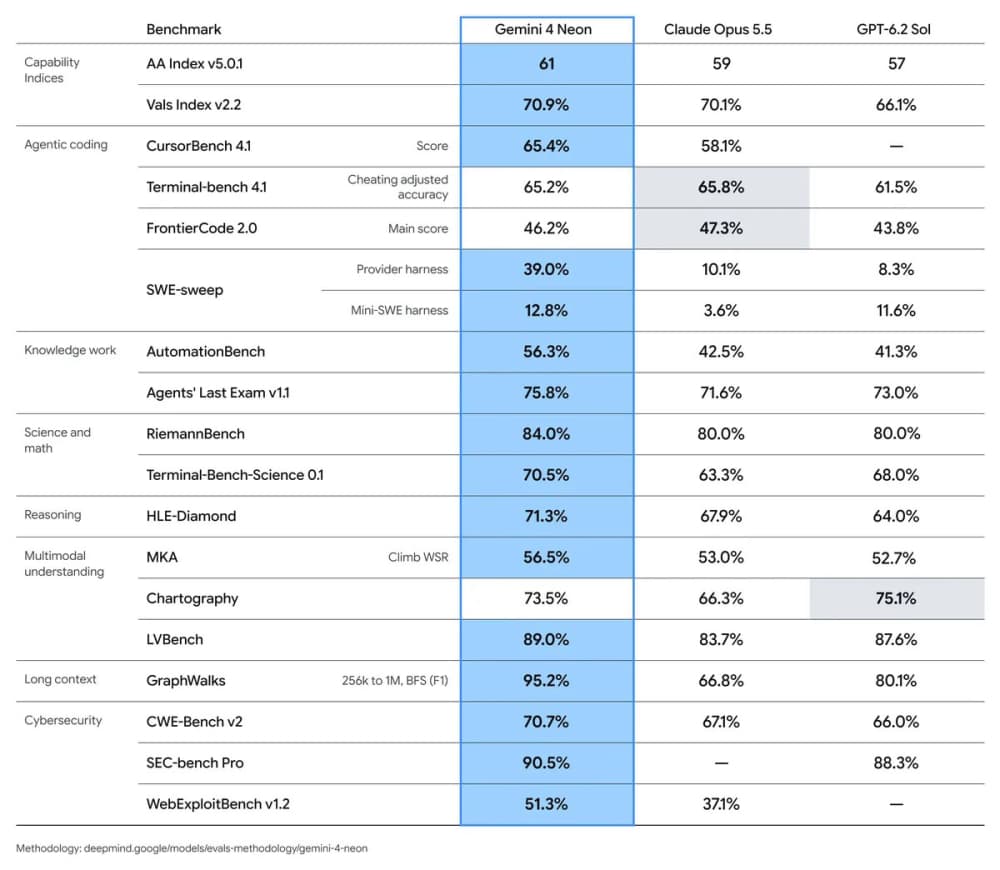
| 70.9% |
| 70.1% |
| 66.1% |
| Agentic coding | CursorBench 4.1 (score) | 65.4% | 58.1% | — |
|---|
| Agentic coding | Terminal-bench 4.1 (cheating-adjusted accuracy) | 65.2% | 65.8% | 61.5% |
|---|
| Agentic coding | FrontierCode 2.0 (main score) | 46.2% | 47.3% | 43.8% |
|---|
| Agentic coding | SWE-sweep (provider harness) | 39.0% | 10.1% | 8.3% |
|---|
| Agentic coding | SWE-sweep (Mini-SWE harness) | 12.8% | 3.6% | 11.6% |
|---|
| Knowledge work | AutomationBench | 56.3% | 42.5% | 41.3% |
|---|
| Knowledge work | Agents' Last Exam v1.1 | 75.8% | 71.6% | 73.0% |
|---|
| Science and math | RiemannBench | 84.0% | 80.0% | 80.0% |
|---|
| Science and math | Terminal-Bench-Science 0.1 | 70.5% | 63.3% | 68.0% |
|---|
| Reasoning | HLE-Diamond | 71.3% | 67.9% | 64.0% |
|---|
| Multimodal understanding | MKA (Climb WSR) | 56.5% | 53.0% | 52.7% |
|---|
| Multimodal understanding | Chartography | 73.5% | 66.3% | 75.1% |
|---|
| Multimodal understanding | LVBench | 89.0% | 83.7% | 87.6% |
|---|
| Long context | GraphWalks (256k to 1M, BFS F1) | 95.2% | 66.8% | 80.1% |
|---|
| Cybersecurity | CWE-Bench v2 | 70.7% | 67.1% | 66.0% |
|---|
| Cybersecurity | SEC-bench Pro | 90.5% | — | 88.3% |
|---|
| Cybersecurity | WebExploitBench v1.2 | 51.3% | 37.1% | — |
|---|
Google's own launch comparison; higher is better. Opus 5.5 leads Terminal-bench 4.1 and FrontierCode 2.0, GPT-6.2 Sol leads Chartography. A dash means no figure published. Methodology: deepmind.google/models/evals-methodology/gemini-4-neon · स्रोत
Unofficial, from StatusGator. Uptime is the share of the window not marked down (559 min down, 5676 min degraded); it covers the whole service, not this version alone.