
La prima voce è sempre la fonte del pin. L’affidabilità complessiva è una media ponderata di quanto ogni fonte conferma gli orari di inizio e fine indicati sopra; una fonte conta la metà per ogni 180 giorni in più rispetto alla più recente.
Google's own post, dated 18 November 2026, says Gemini 4 Neon is rolling out today.
Google DeepMind's model card linked from the announcement.[1]
Google's post on the safety and security approach for the Gemini 4 family, linked from the announcement.[1]
Google's announcement of the lower-cost sibling model released 12 November 2026.[1]
Google's post on the top-tier Gemini 4 Carbon model, the sibling above Neon.[1]
Manca qualcosa o c’è un errore? Dillo con parole tue: un link che conferma questo pin, una data di inizio o fine diversa e perché, o un fatto che manca o è sbagliato. L’IA lo confronta con le fonti del pin, ne cerca di migliori e aggiunge qualsiasi pagina ti dia ragione. Le fonti del pin contano comunque di più. Anche un’immagine che mostra altro, o lo mostra male, viene esaminata e spostata in basso o sostituita.
Unofficial, from StatusGator. Uptime is the share of the window not marked down (529 min down, 5676 min degraded); it covers the whole service, not this version alone.
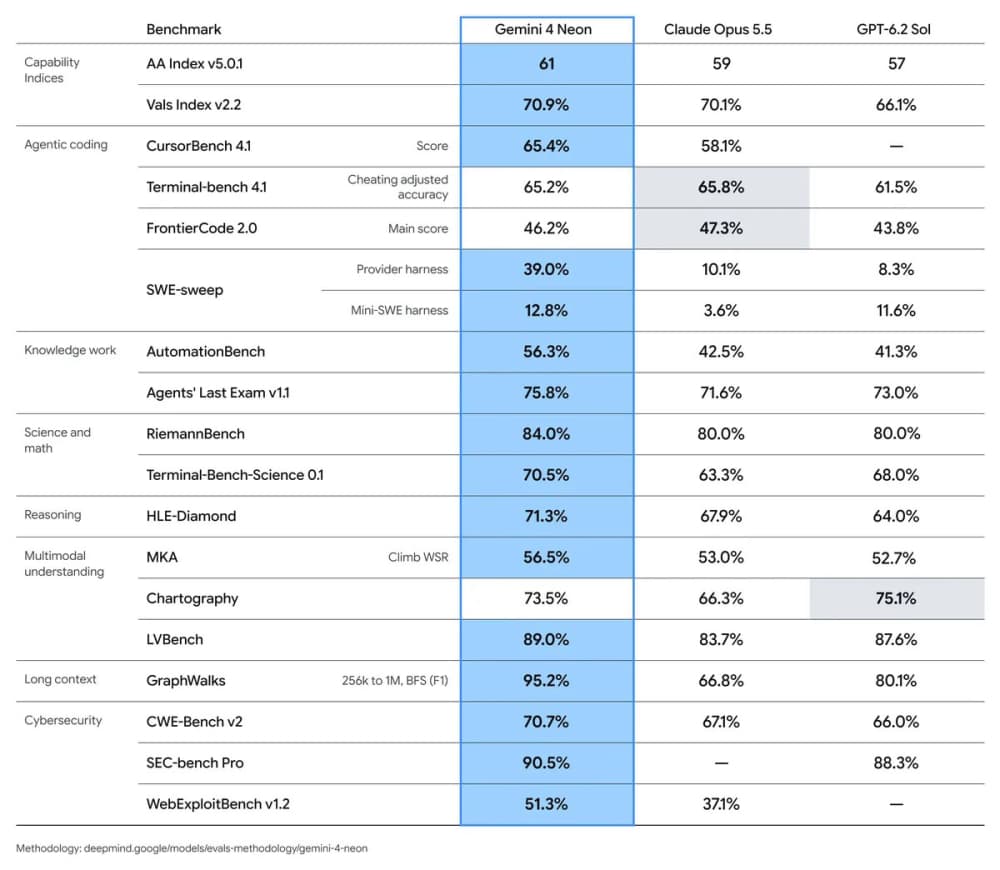
Google-reported launch comparison against Claude Opus 5.5 and GPT-6.2 Sol. A dash means Google published no figure for that model. These are the maker's own results, not independently checked here.[1]
| Benchmark (area) | Gemini 4 Neon | Claude Opus 5.5 | GPT-6.2 Sol |
|---|---|---|---|
| AA Index v5.0.1 (Capability indices) | 61 | 59 | 57 |
| Vals Index v2.2 (Capability indices) | 70.9% | 70.1% | 66.1% |
| CursorBench 4.1 (score) (Agentic coding) | 65.4% | 58.1% | — |
| Terminal-bench 4.1 (cheating-adjusted accuracy) (Agentic coding) | 65.2% | 65.8% | 61.5% |
| FrontierCode 2.0 (main score) (Agentic coding) | 46.2% | 47.3% | 43.8% |
| SWE-sweep (provider harness) (Agentic coding) | 39.0% | 10.1% | 8.3% |
| SWE-sweep (Mini-SWE harness) (Agentic coding) | 12.8% | 3.6% | 11.6% |
| AutomationBench (Knowledge work) | 56.3% | 42.5% | 41.3% |
| Agents' Last Exam v1.1 (Knowledge work) | 75.8% | 71.6% | 73.0% |
| RiemannBench (Science and math) | 84.0% | 80.0% | 80.0% |
| Terminal-Bench-Science 0.1 (Science and math) | 70.5% | 63.3% | 68.0% |
| HLE-Diamond (Reasoning) | 71.3% | 67.9% | 64.0% |
| MKA (Climb WSR) (Multimodal understanding) | 56.5% | 53.0% | 52.7% |
| Chartography (Multimodal understanding) | 73.5% | 66.3% | 75.1% |
| LVBench (Multimodal understanding) | 89.0% | 83.7% | 87.6% |
| GraphWalks (256k to 1M, BFS F1) (Long context) | 95.2% | 66.8% | 80.1% |
| CWE-Bench v2 (Cybersecurity) | 70.7% | 67.1% | 66.0% |
| SEC-bench Pro (Cybersecurity) | 90.5% | — | 88.3% |
| WebExploitBench v1.2 (Cybersecurity) | 51.3% | 37.1% | — |
Neon leads on most rows, but Claude Opus 5.5 is ahead on Terminal-bench 4.1 (65.8% against 65.2%) and FrontierCode 2.0 (47.3% against 46.2%), and GPT-6.2 Sol is ahead on Chartography (75.1% against 73.5%). Google's methodology page is deepmind.google/models/evals-methodology/gemini-4-neon.[1]