
Mục đầu tiên luôn là nguồn của ghim. Độ tin cậy tổng thể là trung bình có trọng số về mức độ mỗi tài liệu ủng hộ thời điểm bắt đầu và kết thúc được dùng ở trên; một tài liệu được tính giảm một nửa cho mỗi 180 ngày cũ hơn tài liệu mới nhất.
Google's own post, dated 18 November 2026, says Gemini 4 Neon is rolling out today.
Google DeepMind's model card linked from the announcement.[1]
Google's post on the safety and security approach for the Gemini 4 family, linked from the announcement.[1]
Google's announcement of the lower-cost sibling model released 12 November 2026.[1]
Google's post on the top-tier Gemini 4 Carbon model, the sibling above Neon.[1]
Thiếu hay sai điều gì? Hãy nói bằng lời của bạn: một liên kết củng cố ghim này, một ngày bắt đầu hoặc kết thúc khác kèm lý do, hoặc một thông tin còn thiếu hay sai. AI đối chiếu với các nguồn của ghim này, tìm nguồn tốt hơn và thêm mọi trang ủng hộ bạn. Các nguồn của chính ghim vẫn được tính nhiều nhất. Hình ảnh thể hiện nội dung khác hoặc thể hiện kém cũng được xem xét, rồi bị hạ xuống hoặc thay thế.
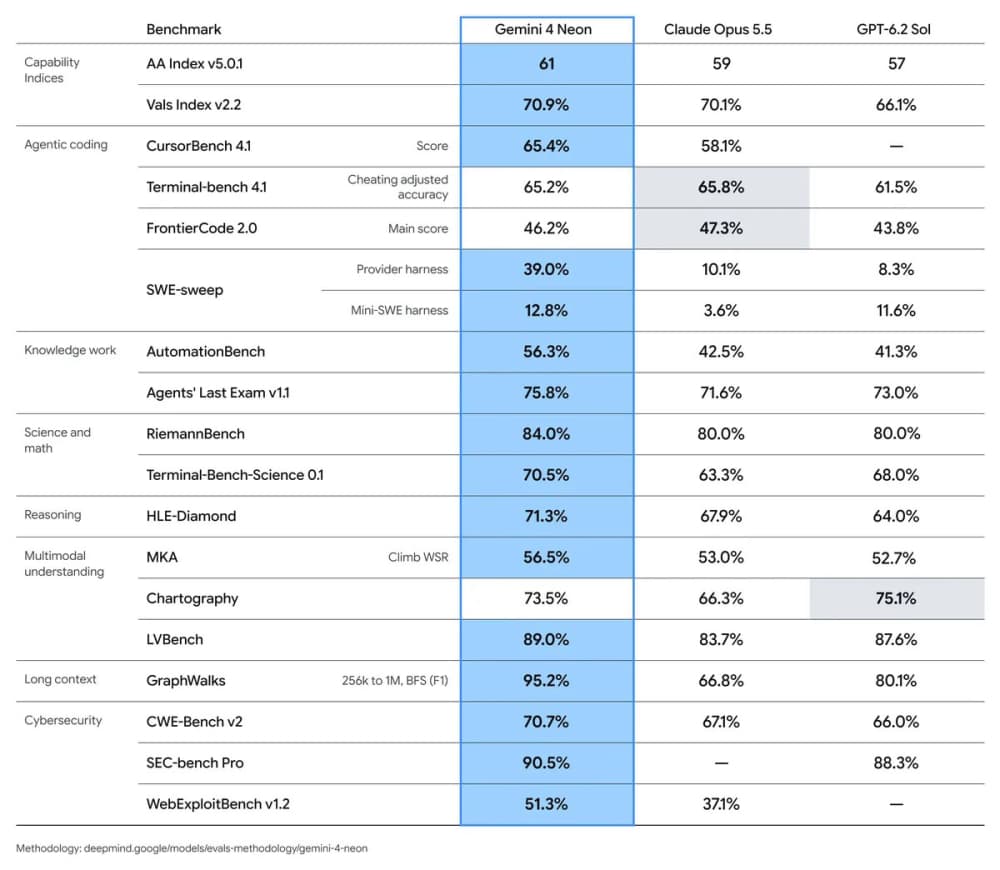
| 70.9% |
| 70.1% |
| 66.1% |
| Agentic coding | CursorBench 4.1 (score) | 65.4% | 58.1% | — |
|---|
| Agentic coding | Terminal-bench 4.1 (cheating-adjusted accuracy) | 65.2% | 65.8% | 61.5% |
|---|
| Agentic coding | FrontierCode 2.0 (main score) | 46.2% | 47.3% | 43.8% |
|---|
| Agentic coding | SWE-sweep (provider harness) | 39.0% | 10.1% | 8.3% |
|---|
| Agentic coding | SWE-sweep (Mini-SWE harness) | 12.8% | 3.6% | 11.6% |
|---|
| Knowledge work | AutomationBench | 56.3% | 42.5% | 41.3% |
|---|
| Knowledge work | Agents' Last Exam v1.1 | 75.8% | 71.6% | 73.0% |
|---|
| Science and math | RiemannBench | 84.0% | 80.0% | 80.0% |
|---|
| Science and math | Terminal-Bench-Science 0.1 | 70.5% | 63.3% | 68.0% |
|---|
| Reasoning | HLE-Diamond | 71.3% | 67.9% | 64.0% |
|---|
| Multimodal understanding | MKA (Climb WSR) | 56.5% | 53.0% | 52.7% |
|---|
| Multimodal understanding | Chartography | 73.5% | 66.3% | 75.1% |
|---|
| Multimodal understanding | LVBench | 89.0% | 83.7% | 87.6% |
|---|
| Long context | GraphWalks (256k to 1M, BFS F1) | 95.2% | 66.8% | 80.1% |
|---|
| Cybersecurity | CWE-Bench v2 | 70.7% | 67.1% | 66.0% |
|---|
| Cybersecurity | SEC-bench Pro | 90.5% | — | 88.3% |
|---|
| Cybersecurity | WebExploitBench v1.2 | 51.3% | 37.1% | — |
|---|
Google's own launch comparison; higher is better. Opus 5.5 leads Terminal-bench 4.1 and FrontierCode 2.0, GPT-6.2 Sol leads Chartography. A dash means no figure published. Methodology: deepmind.google/models/evals-methodology/gemini-4-neon · nguồn
Unofficial, from StatusGator. Uptime is the share of the window not marked down (559 min down, 5676 min degraded); it covers the whole service, not this version alone.