
첫 번째 항목은 항상 핀의 출처입니다. 전체 신뢰도는 각 자료가 위의 시작·종료 시각을 얼마나 확실히 뒷받침하는지에 대한 가중 평균이며, 자료는 최신 자료보다 180일 오래될 때마다 가중치가 절반이 됩니다.
Google's own post, dated 18 November 2026, says Gemini 4 Neon is rolling out today.
Google DeepMind's model card linked from the announcement.[1]
Google's post on the safety and security approach for the Gemini 4 family, linked from the announcement.[1]
Google's announcement of the lower-cost sibling model released 12 November 2026.[1]
Google's post on the top-tier Gemini 4 Carbon model, the sibling above Neon.[1]
빠지거나 잘못된 점이 있나요? 이 핀을 뒷받침하는 링크, 다른 시작일이나 종료일과 그 이유, 빠지거나 잘못된 사실을 자신의 말로 알려주세요. AI가 이 핀의 출처와 대조하고 더 나은 자료를 찾아, 뒷받침하는 페이지를 추가합니다. 핀 자체의 출처가 여전히 가장 중요하게 반영됩니다. AI는 이미지도 확인합니다. 다른 것을 보여주거나 제대로 보여주지 못하는 이미지는 뒤로 옮기거나 교체합니다.
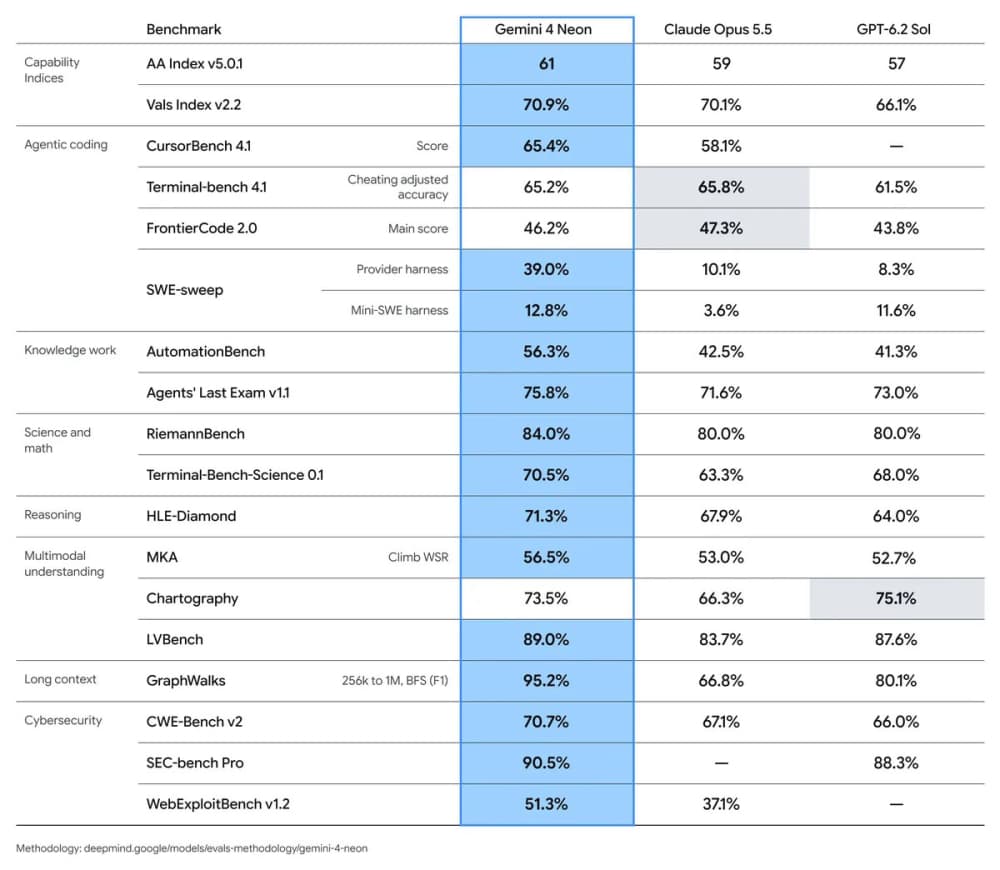
| 70.9% |
| 70.1% |
| 66.1% |
| Agentic coding | CursorBench 4.1 (score) | 65.4% | 58.1% | — |
|---|
| Agentic coding | Terminal-bench 4.1 (cheating-adjusted accuracy) | 65.2% | 65.8% | 61.5% |
|---|
| Agentic coding | FrontierCode 2.0 (main score) | 46.2% | 47.3% | 43.8% |
|---|
| Agentic coding | SWE-sweep (provider harness) | 39.0% | 10.1% | 8.3% |
|---|
| Agentic coding | SWE-sweep (Mini-SWE harness) | 12.8% | 3.6% | 11.6% |
|---|
| Knowledge work | AutomationBench | 56.3% | 42.5% | 41.3% |
|---|
| Knowledge work | Agents' Last Exam v1.1 | 75.8% | 71.6% | 73.0% |
|---|
| Science and math | RiemannBench | 84.0% | 80.0% | 80.0% |
|---|
| Science and math | Terminal-Bench-Science 0.1 | 70.5% | 63.3% | 68.0% |
|---|
| Reasoning | HLE-Diamond | 71.3% | 67.9% | 64.0% |
|---|
| Multimodal understanding | MKA (Climb WSR) | 56.5% | 53.0% | 52.7% |
|---|
| Multimodal understanding | Chartography | 73.5% | 66.3% | 75.1% |
|---|
| Multimodal understanding | LVBench | 89.0% | 83.7% | 87.6% |
|---|
| Long context | GraphWalks (256k to 1M, BFS F1) | 95.2% | 66.8% | 80.1% |
|---|
| Cybersecurity | CWE-Bench v2 | 70.7% | 67.1% | 66.0% |
|---|
| Cybersecurity | SEC-bench Pro | 90.5% | — | 88.3% |
|---|
| Cybersecurity | WebExploitBench v1.2 | 51.3% | 37.1% | — |
|---|
Google's own launch comparison; higher is better. Opus 5.5 leads Terminal-bench 4.1 and FrontierCode 2.0, GPT-6.2 Sol leads Chartography. A dash means no figure published. Methodology: deepmind.google/models/evals-methodology/gemini-4-neon · 출처
Unofficial, from StatusGator. Uptime is the share of the window not marked down (559 min down, 5676 min degraded); it covers the whole service, not this version alone.